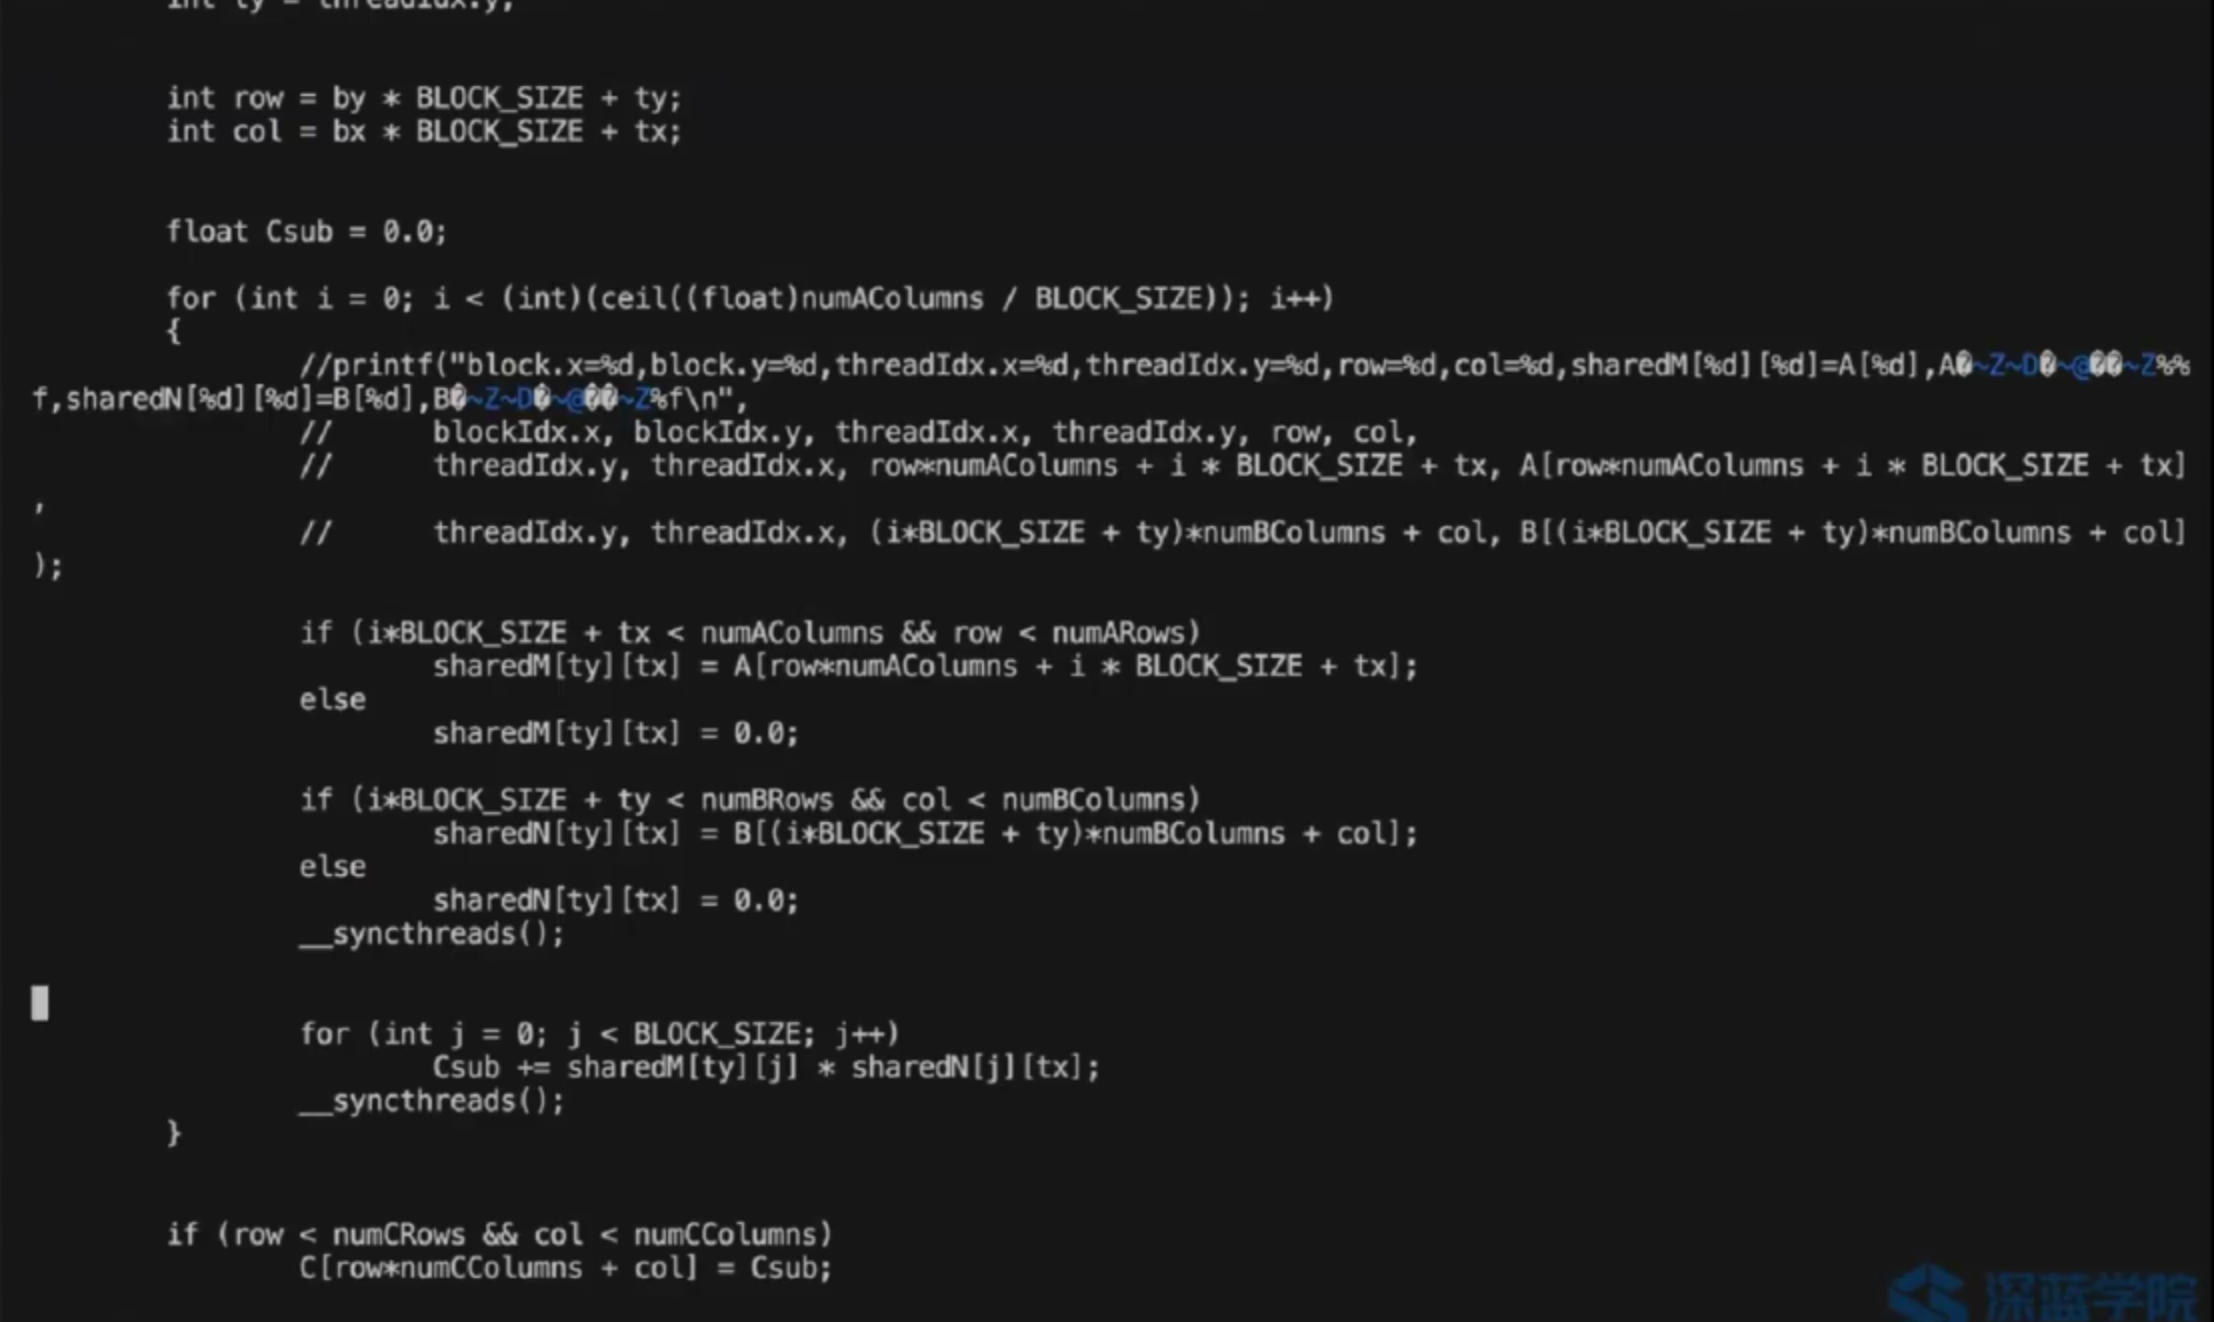
- Tiled matrix multiplication
- Here each thread is responsible for one row of A and one column of B, but it processes that row and column in batches inside the for loop, because shared memory is used
- When i=0, the first patch is processed; note that tx is the column and ty is the row
if (i*BLOCK_SIZE + tx < numAColumns && row < numARows)
    sharedM[ty][tx] = A[row*numAColumns + i * BLOCK_SIZE + tx];
else
    sharedM[ty][tx] = 0.0;

if (i*BLOCK_SIZE + ty < numBRows && col < numBColumns)
    sharedN[ty][tx] = B[(i*BLOCK_SIZE + ty)*numBColumns + col];
else
    sharedN[ty][tx] = 0.0;
__syncthreads();
For example, for the first block of matrix C, at i=0 the threads reach __syncthreads() once the first patches of A and B have been loaded into shared memory; then sharedM and sharedN are multiplied and accumulated, and i=1 is processed next. Note: this is still the first block. One thread handles one row of A and one column of B, and it is now processing the second patch of that row and column; sharedM and sharedN are refilled, and this is the shared memory of the same block
Patches are divided along the columns of A, because the number of rows of B equals the number of columns of A
A[row*numAColumns + i * BLOCK_SIZE + tx] fetches the value from the corresponding patch of A; here i indexes the columns of A, i.e. which patch along the columns
B[(i*BLOCK_SIZE + ty)*numBColumns + col] is different because here i indexes the rows of matrix B, i.e. which patch along the rows
__global__ void matrixMultiplyShared(float *A, float *B, float *C,
    int numARows, int numAColumns, int numBRows, int numBColumns, int numCRows, int numCColumns)
{
    //@@ Insert code to implement matrix multiplication here
    //@@ You have to use shared memory for this MP

    __shared__ float sharedM[BLOCK_SIZE][BLOCK_SIZE];
    __shared__ float sharedN[BLOCK_SIZE][BLOCK_SIZE];

    int bx = blockIdx.x;
    int by = blockIdx.y;
    int tx = threadIdx.x;
    int ty = threadIdx.y;


    int row = by * BLOCK_SIZE + ty;
    int col = bx * BLOCK_SIZE + tx;


    float Csub = 0.0;

    for (int i = 0; i < (int)(ceil((float)numAColumns / BLOCK_SIZE)); i++)
    {
        //printf("block.x=%d,block.y=%d,threadIdx.x=%d,threadIdx.y=%d,row=%d,col=%d,sharedM[%d][%d]=A[%d],value of A: %f,sharedN[%d][%d]=B[%d],value of B: %f\n",
        //	blockIdx.x, blockIdx.y, threadIdx.x, threadIdx.y, row, col,
        //	threadIdx.y, threadIdx.x, row*numAColumns + i * BLOCK_SIZE + tx, A[row*numAColumns + i * BLOCK_SIZE + tx],
        //	threadIdx.y, threadIdx.x, (i*BLOCK_SIZE + ty)*numBColumns + col, B[(i*BLOCK_SIZE + ty)*numBColumns + col]);

        if (i*BLOCK_SIZE + tx < numAColumns && row < numARows)
            sharedM[ty][tx] = A[row*numAColumns + i * BLOCK_SIZE + tx];
        else
            sharedM[ty][tx] = 0.0;

        if (i*BLOCK_SIZE + ty < numBRows && col < numBColumns)
            sharedN[ty][tx] = B[(i*BLOCK_SIZE + ty)*numBColumns + col];
        else
            sharedN[ty][tx] = 0.0;
        __syncthreads();


        for (int j = 0; j < BLOCK_SIZE; j++)
            Csub += sharedM[ty][j] * sharedN[j][tx];
        __syncthreads();
    }


    if (row < numCRows && col < numCColumns)
        C[row*numCColumns + col] = Csub;

}